The Economics of Continuous Inference
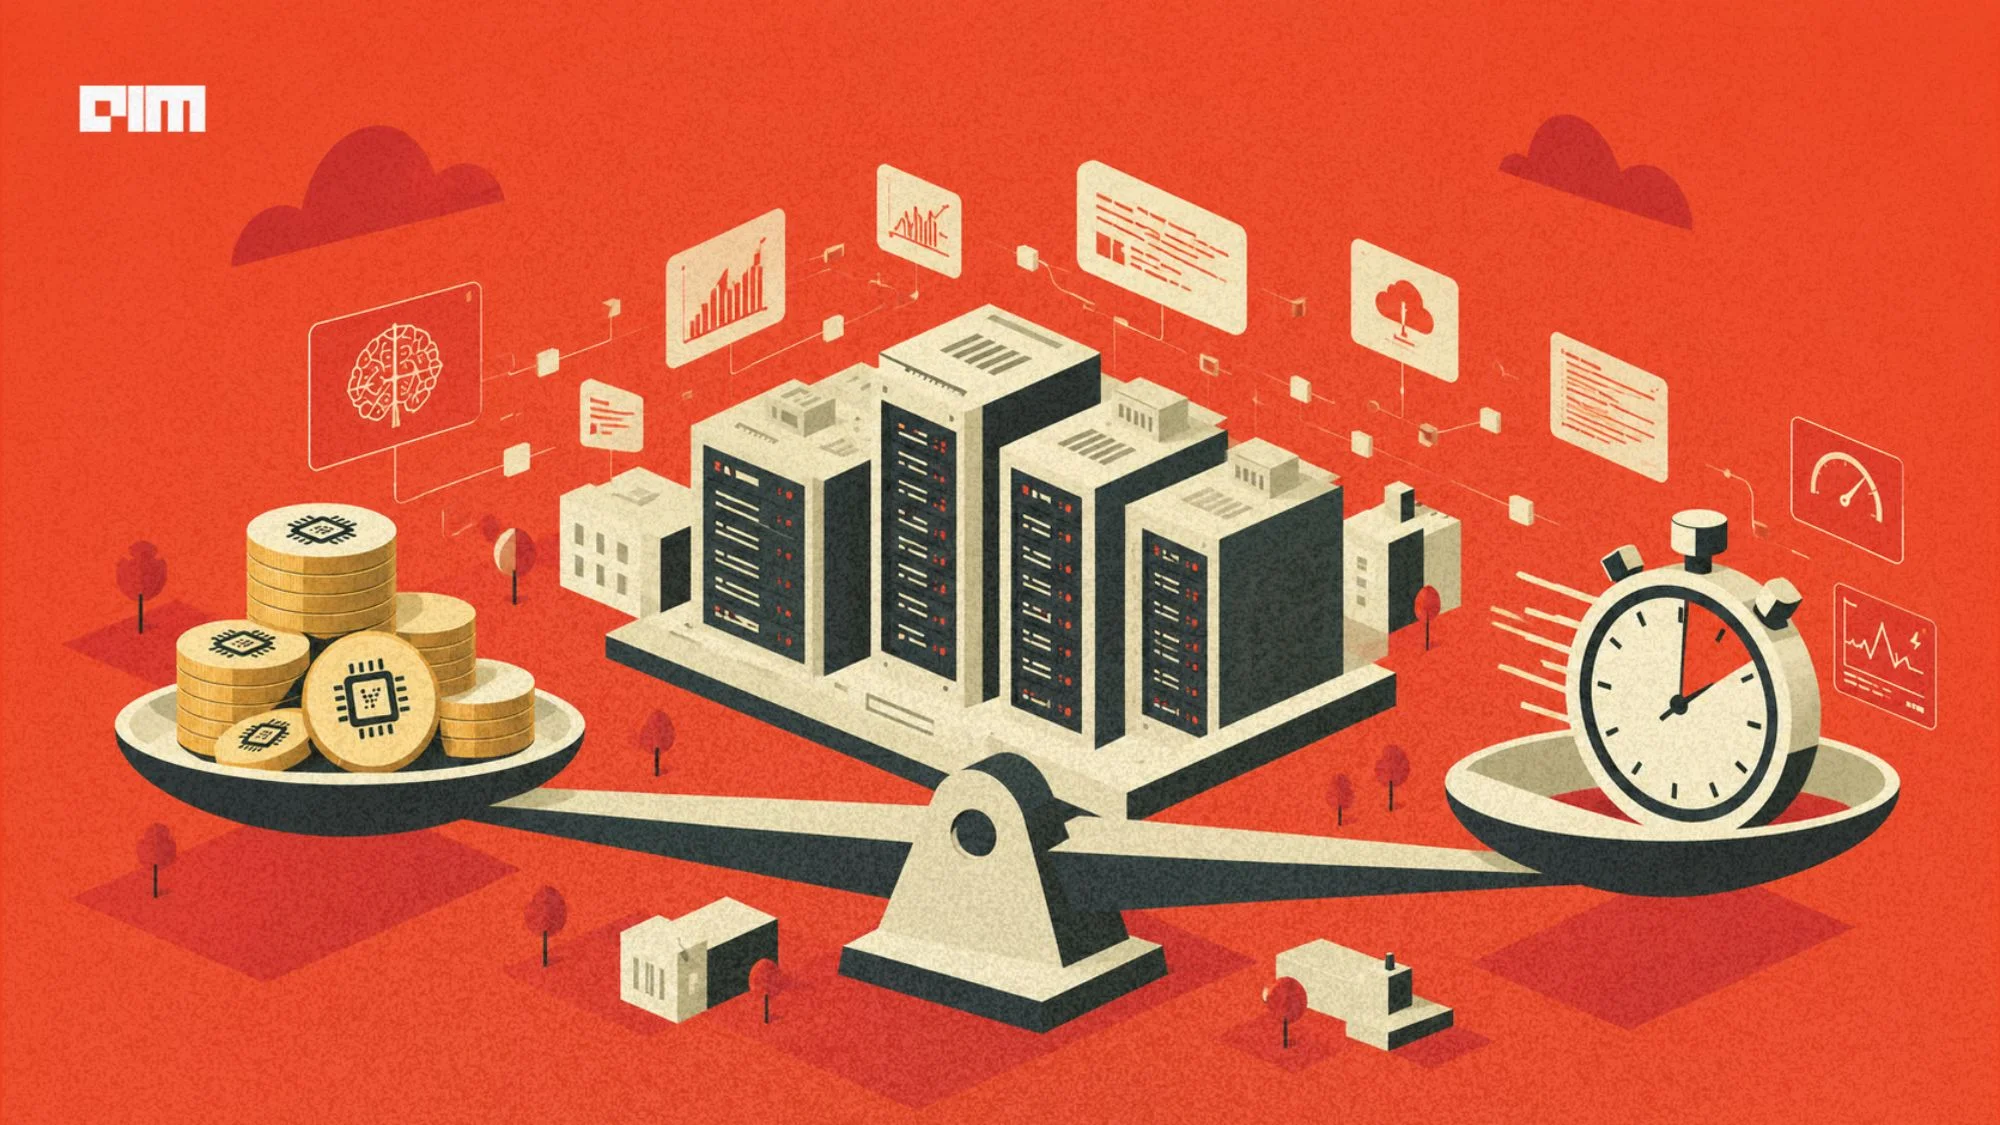
Serving AI models in production involves managing latency, concurrency, and variable demand. Factors such as KV-cache pressure and bursty traffic increase the effective cost per request, making simple GPU hourly rates an incomplete measure of expense.
Key points
- Production serving must meet specific latency and availability targets.
- Workload types like batch inference and interactive chat have different economic requirements.
- The true cost is measured by the cost per successful task at a specific service level.
Summary and key points written by AI from the headline and a short excerpt, so they can be incomplete or wrong. Analytics India Magazine did the reporting; read the original for the full story.
Read the full story at Analytics India Magazine