Tens of thousands of Nvidia GPUs sit idle in Meta's Prometheus supercluster, just waiting for a failure
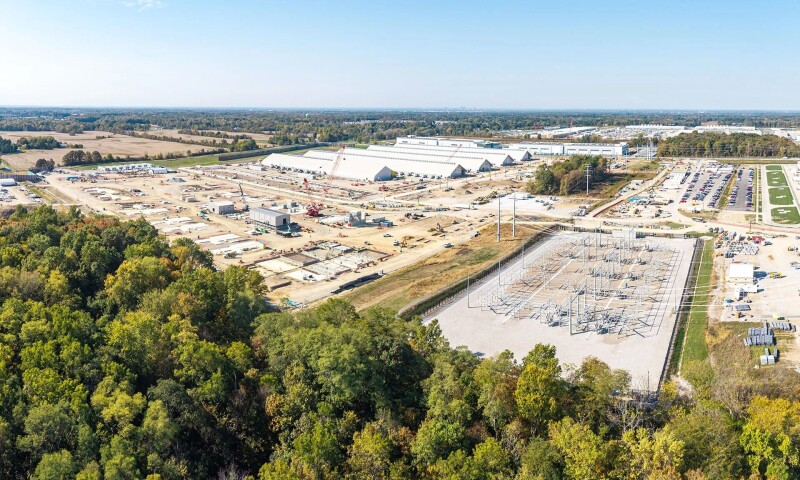
Meta's Prometheus supercluster in Ohio, powered by Nvidia's Grace Blackwell and upcoming Vera Rubin systems, maintains a large pool of idle GPUs (over 11% of capacity) dedicated to rapid failover. The facility, destined to scale to a gigawatt with roughly a million accelerators, faces inevitable hardware failures at scale. Meta revealed it experienced approximately 1,000 interruptions per day on every 8,000 GPUs during initial deployment, prompting the company to invest heavily in redundancy to ensure uninterrupted training for models like Muse Spark and Muse Wonder.
Key points
- 11%+ GPU capacity reserved for failover and redundancy
- Prometheus eventually scaling to ~1M accelerators at 1GW
- Meta experienced 1,000 daily interruptions per 8K GPUs initially
- Redundancy critical for distributed multi-datacenter training
Summary and key points written by AI from the headline and a short excerpt, so they can be incomplete or wrong. The Register did the reporting; read the original for the full story.
Read the full story at The Register